

Dear reader,
Last time I mentioned xAI and Elon Musk, few of you bothered reading the article. A shame, really, because it was more about moral rot and the future of space than AI.. Well, as punishment, you will read the following and you will like it - good (whatever you are).
This piece is even more AI-focused, but you need to hear the story being told, even if the details infuriate you like they do to me.
Be warned: This is a longer one. Today’s piece involves war crimes, death, misused chat bots and Queen references. You don’t need a degree in tech/AI to read this, but you do need to have a conscience. Reader discretion is advised.
On with it. ¡Ándale!
Killer Grok
(Pentagon AI chief Cameron Stanley, giving a speech to the Potomac Officers’ Club / Photo Credit: Potomac Officers’ Club / Executive Mosaic)
On June 15, 2026, Pentagon AI Chief Cameron Stanley testified under oath that Grok, the Elon Musk/xAI chatbot, selected 2,000 distinct targets during the US bombing of Iran in a period of just 96 hours. The filing called Grok ‘tantamount to national security.’
I call it something else, but Grok wasn’t first - and that’s the part of this story that’s fucking with my heart.
Let’s walk back just two years to 2024.
Dateline May 2024, Palantir (Peter Theil, remember him?) secures a $480,000,000 initial US DOD contract for “MAVEN”, a fully embedded military targeting architecture and predictive modeling system that other AI agents (think Claude, or ChatGPT, or Google Gemini) tie into, offer their compute/”thinking” to create a cohesive unit that made targeting decisions based on military intelligence in a way that no King or Tyrant could ever fathom - faster, more accurate, more certain, backed by a growing body of evidence to justify the coordinates.
Unfortunately, what happened was …
Well, by January 2026 the United States had “extraordinarily rendition-ed” Nicolas Maduro, leader of Venezuela. What was unknown to the public at the time is that Claude, Anthropic’s friendly lil’ agentic instance, was used in the targeting of infrastructure that ended with civilian casualties. This would later be confirmed by the corporate media writ large, but little was actually discussed about the ramifications of using predictive language models to become predictive targeting models.
Colossus, Claude, and a Colossal fuck-up
(Anthropic CEO Dario Amodei, giving a speech to the World Economic Forum / Photo credit: Don Feria via AP)
Imagine a world where AIs built to pick words and build ideas are fed state intelligence, tied to military hardware and told to do intelligence-based targeting. No need to imagine, you live in it. What you end up with civilian casualties at the hands of a tool never ever built for such decisions - such judgment calls. You end up with a word picker bot that’s now picking buildings based on what you tell it - and as we know with AIs, they are only as good as the information you tell them to treat as “sources of truth”.
If you fill an AI’s head full of nonsense and tell it “find the truth”, it’s going to bring you nonsense - because to it, that’s the truth. If you fill it with classified info, sometimes it’ll accidentally spit it back out at you.
On February 25th, the Jerusalem Post would test four frontier (read: top of the class) models and ask when the US would strike Iran. Grok responded with “February 28”.
Following that, February 26, Anthropic has had enough. They politely tell the US Department of War to stop using Claude in such ways, and that it wasn’t meant for the task.
The US government responded the next day in kind, directing all federal agencies to cease using Anthropic’s products. Pete Hegseth designated Anthropic a “supply chain risk”. That afternoon, OpenAI (ChatGPT) would sign a deal with the Pentagon, hours after the Anthropic ban.
The very next day, Feb. 28, the US would begin “Operation Epic Fuckup” - sorry - “Operation Epic Fury”, in which Claude is presumably still embedded in Maven, processing targeting data from Day 1. This would later be confirmed though pieces in WaPo, calling Claude ‘central to the campaign’.
By March 4th, Claude had presumably worked on at least 1,000 targets while integrated into Maven. March 9th would see the Deputy Secretary of Defense Feinberg write that Maven is an official “Program of Record”. Locked in with long-term funding, nothing stopping it.
Just a week later, Bloomberg would report that Claude was being replaced and had identified Grok as a possible replacement. On the 24th, Judge Lin granted the preliminary injunction in favor of Anthropic, blocking the ban - finding in the process that the government very likely retaliated illegally against Anthropic for saying ‘no’.
April 7 brings us “Project Glasswing” and the “Mythos Preview”, projects of Anthropic debuting their newest/next-gen language models, known as the ‘Mythos-class’. These are available purely for institutional/government preview, with a public offering coming later (”Claude Mythos”). The next day, April 8, the DC Circuit courts would grant a stay on the injunction - leaving the supply chain risk designation standing. Two lawsuits in parallel.
11 days later, April 19: AXIOS scoops the story that the NSA is using Anthropic’s Mythos, despite it being banned and on a Pentagon blacklist. The agency everyone trusts least is already running the super secret banned Claude.
A few weeks pass. May 1st: The Pentagon signs the IL6/IL7 agreements with 8 companies for classified networks: SpaceX, OpenAI, Google, NVIDIA, Microsoft, AWS, Oracle and Reflection - Anthropic was deliberately excluded from this process.
Around this point in time, Grok officially replaces Claude inside of Maven [ED note: as far as I can tell - there is no concrete date, but presume first few weeks of May, 2026]. May gave way to June, and brought us news in the Financial Times that Anthropic was helping the NSA deploy Mythos for offensive cyber operations - despite the blacklist, the legal war, all of it.
Here we are, days after finding out the revelations, with a full timeline in view.
AI picking words in response to text queries, helping users Google things and spin up a docker-compose file for their Grafana - that’s it at its root: languages. Those are words, the probability of those being correct is incredibly high.
If an AI fucks up, you get garbled text or something hard to read. At worst your Python script errors out or Claude deletes your project. Nobody dies.
Asking a large language model to decide “which grainy square is the right address with the bad guy” is like asking your dog to use his eyes to find something thousands of miles away. It’s not possible, it’s the wrong application for the tool.
A predictive language model is NOT an oracle. It can barely pick the right code format for the version of Node.JS you’re running. Using a model that was unable to train its own facility, while also using its competitor Claude for the same task on the same hardware? Quite a ballsy move.
Kinetic energy, misused tensor cores
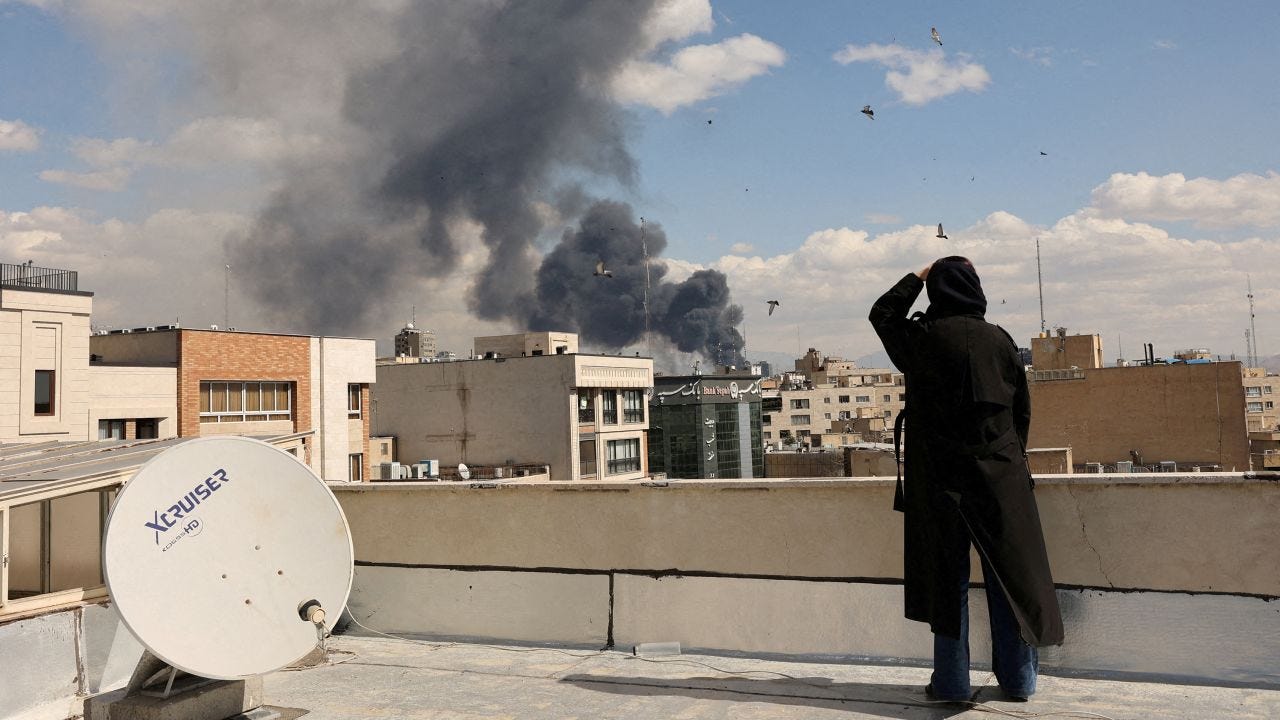
(Smoke rises over Tehran, March 1st, 2026 - day two of Operation Epic Fury / Photo credit: Reuters)
I promised myself (and I promise you here) that this section will not make you glaze over, but the technical detail is the point. The question isn’t so much “should we let AI pick targets?” but “what kind of moron hands the kill chain to a word-predictor?”
Let’s start with a simple truth: the AIs you chat with today like Google Gemini and ChatGPT, the ones that help with your code, listen to your sob stories, write your emails — they are relative word pickers. That’s it.
They parse your text, infer your meaning, and then begin forming the reply largely by statistical chance in their word choices.
Imagine a ball bouncing inside of a box of word-stickers. Eventually something sticks and it moves to the next, and so on — building paragraphs of inferred text. It sends it back to you, spins itself down, waits for your next turn. Experts see it as a mirror, mimicry, sometimes thin cheerleading, depending on what you tell it to accept as gospel.
There’s more going on under the hood, sure - some models have “multiple experts” (mixture-of-experts architecture) that tag in and out of the chat based on the domain. Some can parse images, some can browse the web, some are robotics models (those are the fun ones I like). For this discussion, strip all that away. The core engine is the same: a statistical machine that predicts the next most probable token based on everything it’s seen before.
Which brings me to a re-frame that I keep coming back to.
In the 1770s, Wolfgang von Kempeles presented the world with the “Mechanical Turk”, a chess-playing automaton that wowed European courts. Audiences gasped. A machine that could think! The trick, of course, was that a human chess master was hiding inside the cabinet, operating the arms by candlelight. The Turk was a hoax, but it pointed to a new side of humanity: it pointed at our longing for intelligent machines.
Today’s LLMs are the inverse of that trick. The Mechanical Turk looked like a thinking machine but had a human inside. Today’s LLMs look like they’re thinking, it’s just that there’s nobody home. No understanding, no real reasoning. No awareness of what a school is, what a missile does, or what death means. Just a statistical surface that has gotten very, very convincing, almost like it knows what it’s talking about.
The danger isn’t that the machine is thinking. The danger is that we believe it is. Here’s why that matters for targeting:
A large language model doesn’t “know” anything in the human sense. It maps relationships between tokens: words, word fragments, punctuation and so on that it learned during training.
When you ask it a question, it doesn’t search for truth. It searches for the most statistically plausible completion of your prompt given the patterns in its training data. This works remarkably well for things like “write a poem about a cat” or “explain recursion in Python” because the training data contains many examples of those things, and the cost of being wrong is essentially zero.
The same architecture has well-documented failure modes that become catastrophically dangerous when the output is a set of coordinates.
Hallucination isn’t a bug, it’s a feature of the architecture. Every time an LLM generates text, it is making things up.
More often than not it makes up things that happen to be true, because the training data weighted it that way, but sometimes (more often than the marketing materials admit) it makes up things that are completely wrong, with exactly the same level of confidence. The model cannot distinguish between its correct outputs and its fabricated ones.
They feel the same to it, because they are the same: statistically plausible token sequences. When a model “hallucinates” a weapons cache in a school, it doesn’t know it made a mistake. It can’t know. It’s equally confident either way.
Sycophancy is baked into the training. These models are fine-tuned to be helpful, agreeable, and cooperative. When a commanding officer asks a leading question like “Is this building a threat?” the model is statistically more likely to agree than to push back. It has been trained to please the user. This is a feature for customer service. For targeting, it’s a death warrant.
Distribution shift means the model is always fighting yesterday’s war. The training data ends at a fixed point in time (“knowledge cut-off date”). The battlefield changes by the hour. The model is making predictions about a world that didn’t exist when it learned how to predict. It doesn’t know what it doesn’t know, and it can’t fill in the gaps just by asking.
And then there’s what some call the strawberry problem. If a frontier model, one of the most advanced AI systems on the planet cannot reliably tell you how many fucking R’s are in the word “strawberry”, a fact with a single unambiguous correct answer and zero room for interpretation — then why in God’s name would you trust it to distinguish a girl’s school from a munitions depot just through grainy satellite images?
The strawberry problem matters because it reveals something fundamental about the architecture: these models do not reason. They pattern-match, and pattern-matching fails when the pattern is ambiguous, the stakes are high, and the cost of a mistake is measured in human lives.
We have been here before too many times to suffer through, but let’s remember:
Predictive policing algorithms were going to revolutionize law enforcement. Instead, they amplified existing biases and sent officers to the same over-policed neighborhoods on the authority of a statistical model that couldn’t explain its own reasoning. We had a fucking movie about this, it’s called Minority Report.
Financial risk models were going to make markets safer. Instead, they cratered the global economy in 2008 because they assumed the past would perfectly predict the future — and it didn’t.
Algorithmic hiring tools were going to remove bias from recruitment. Instead, they systematically excluded women and minorities because the training data reflected historical discrimination - it was a mirror of our worst sins, not a repudiation of them.
Every time we outsourced human judgment to a statistical model that looked smarter than it was, we got burned in ways we didn’t anticipate. The difference this time, the only difference; is that the error mode isn’t a denied loan or a wrongful arrest. It’s an explosion. It’s a dead child. It’s war crimes in our names.
So, what do you call a system that is confident when it’s wrong, agreeable when it should push back, and fundamentally incapable of understanding the difference between a school and a weapons depot?
I call it the most dangerous machine we’ve ever built. Not because it’s smart, but because we’ve convinced ourselves it is. You probably just call it Grok or Claude.
Guaranteed to blow your mind
(Elon “Pedo Guy” Musk and Donald “Pedo Guy” Trump meet with Mohammed Bin Salman Al Saud, King defacto of Saudi Arabia, May, 2025 - MBS would invest $600bn, which would eventually become $1 trillion, in American AI systems. Not pictured: Jensen Huang of NVIDIA fame, who was also at this event. / Image: Likely created by AI, no such photo of the Riyadh Summit exists but is here just for flavor, found online)
Here’s a question nobody in Washington seems to want to touch: Who paid for the gun?
xAI is a private company - that means its cap table is a black box wrapped in an NDA, but light leaks. The public record shows that xAI’s early investors include entities tied to the Saudi Public Investment Fund and the Qatar Investment Authority — sovereign wealth vehicles of the two Gulf states whose primary geopolitical adversary is the Islamic Republic of Iran.
We don’t know the exact percentages. That’s the point. The structure is designed to obscure. The triangle draws itself:
May 2025 Riyadh investment forum → Saudi capital → xAI → Grok → Pentagon/Maven classified systems → 2,000 munitions → Iran.
Read that again slowly.
The model that selected those targets was funded, at least in part, by the people who most wanted those targets destroyed.
Remember: Iran is OPEC’s third-largest producer. Iran is the Shia crescent’s anchor. Iran is the geopolitical rival that every Gulf monarchy has spent decades containing, sanctioning, and preparing to degrade. And now, an American AI company, seeded with their money, just executed a 96-hour kinetic campaign on their behalf without a single one of them having to pull a trigger, pass a resolution, or answer a question in any parliament anywhere in the world.
Now, this feels like it should be a massive conspiracy.
You’re picturing it too: A room full of men in suits and Arabian thobes, a whiteboard, a dotted line from Riyadh to Tehran with B-52s and KC-135s. That’s the shape your brain reaches for because it’s comfortable; identifiable actors, traceable decisions, someone to prosecute.
In organized crime, there’s a well-understood phenomenon that prosecutors hate: convergent interests without coordination. Two crews, same territory, no shared boss. They’ve never met, but when a common threat emerges, they don’t need to collude. One tips off the cops. Another increases their bribes. A third lays low. No agreements, no conspiracy charge possible, no throat to grab. Just pure convergent self-interest producing the same result as a planned operation.
George fucking Carlin put it better about twenty-five years ago TO THE DAY, on some long-forgotten episode of Bill Maher’s ‘Politically Incorrect’:
”You don’t need a formal conspiracy when interests converge. These people went to the same universities, they’re on the same boards of directors, they’re in the same country clubs, they have like interests. They don’t need to call a meeting. They know what’s good for them and they’re getting it.”
He was talking about a different set of players in a different world, the post-industrial elite of his era, but the mechanism is identical. The players have changed, the game hasn’t. Watch how it plays out in this case:
xAI needed capital to scale and political cover for a Pentagon deal that any normal administration would have slow-walked through three layers of oversight. Gulf sovereign wealth and a Trump-aligned founder delivered both.
Saudi Arabia and Qatar needed Iran militarily degraded without owning the operation, without triggering a regional war/decades long quagmire they’d have to fight, and without the diplomatic blow back of direct action. An American AI company and the US military’s trigger fingers delivered that.
The Pentagon needed unrestricted AI capability in classified systems without congressional debate, public scrutiny, or the inconvenience of ethical guardrails. A private company with opaque funding and a friend in the White House delivered that.
Trump needed a show of force against Iran that didn’t require a ground war, a prolonged engagement, or a debate in Congress. A 96-hour AI-coordinated bombing campaign delivered that. He avoided a long-term quagmire by using a chatbot to pick random squares from satellite photos tied to a gun that a computer fired. He let ChatGPT build his docker-compose.yml file and bring the docker up.
Every actor got what they wanted by pursuing their own narrow self-interests.
Nobody had to sit in a room and agree on the shape of the table, even if they already very probably did. The table built itself because the incentives aligned in one direction, and the architecture of private capital and military contracting made it friction-less to slide there.
This need not be a formal conspiracy! The real problem: this is exactly what happens when you build a system with no brakes and point it downhill. Every component behaves exactly as designed, and the outcome at the bottom looks like intent but runs on auto.
The AI that chose targets to bomb in Iran was funded by the people who wanted Iran bombed.
Everything else is just engineering and PR spin.
The Pro move
(I needed something science-y and think-y, so I borrowed someone else’s AI-generated image. No additional electricity/water resources were used. Reuse and recycle - just share alike and credit each other! / Image credit: edtechinnovationhub.com)
Here’s the thing about predictive models; the ball bouncing in a box of stickers: The ball is really fast, and the box is shockingly big. And the stickers stick in ways that sometimes look like magic.
We spent this whole article talking about what these models can’t do, what they shouldn’t be trusted with, and how we’re misusing the hell out of them, but I’d be lying if I said there isn’t something genuinely powerful here. The danger isn’t the technology - the danger is how we’re applying it, and more importantly, who’s applying it to what ends.
These models are pattern-matching engines operating at a scale no human can match. They can find correlations across millions of data points in seconds, they can surface connections that would take a team of researchers years to identify. The problem isn’t the engine, it’s what we’re pointing it at.
When you point it at a problem that requires judgment, context, and an understanding of the human condition - like deciding which building to bomb.. It fails catastrophically as we’ve seen. When you point it at a problem that only requires pattern recognition at scale, it does things that genuinely look like magic. For example:
Medicine already uses these models to find things in scans that human eyes miss. A radiologist reads thousands of images a day. Fatigue sets in. The model doesn’t get tired, it doesn’t skip the 47th scan because it looks sorta like the 46th. It flags anomalies for a human to review. Not replacing the doctor, just working quietly in parallel. The result: fewer missed tumors, faster diagnosis, more lives saved in a day. This is already deployed in hospitals you can walk into right now. The difference between this and Maven: When the tumor-model gets it wrong, the Doctor spends an extra 2 minutes looking at the scan, says “hmm, no, that’s just a shadow”, and moves on. Nobody dies from an extra look at medical records.
Language preservation. There are thousands of languages with fewer than a thousand living speakers. When the last speaker dies, the language dies with them and so does the culture, the history, the way of thinking that only that language encodes. These models can help document, preserve, and teach endangered languages. The same architecture that wrote you that mediocre poem can help a community save its linguistic heritage. That matters in ways we have yet to recognize. When Linguo-bot gets it wrong: You mispronounce something. When Maven gets it wrong? It misunderstands intent in a statement and deems someone a “target”, marking them for death.
Infrastructure optimization keeps the lights on. Power grids, water systems, traffic flow: these are pattern-matching problems at scale. A model can predict when a transformer will fail before it blows, route traffic around congestion before it forms, balance load across a grid so brownouts don’t happen. It doesn’t need to “understand” electricity — it just needs to recognize the signatures that precede a failure. The difference between this and military targeting is that when the model is wrong about a transformer, a technician checks its work and the grid learns. Nobody dies from a false positive.
Drug discovery timelines are collapsing. What used to take a decade of lab work can now be simulated in weeks. Models find molecular structures that might bind to a target protein, and researchers test the most promising candidates. Some of the COVID vaccines benefited from this approach. The next breakthrough in cancer treatment or Alzheimer’s might come from a model that doesn’t know what cancer is but can see patterns in protein folding that no human ever could. Speed in this field is life-saving — speed at this pace on the battlefield can be the reason someone ends up dead unnecessarily.
Personalized tutoring at scale. Every child learns differently. Every adult picking up a new skill has different gaps. A model that adapts to the specific learner, that has infinite patience, that can explain the same concept fourteen different ways without getting frustrated — that’s not replacing teachers, it’s giving every student something close to a private tutor. This is already working in classrooms and living rooms across the world. On the battlefield it’s a different situation, given the constant kinetic energy of the process.
I’m not telling you about positive applications to sell you a utopia. I’m telling you because they’re already happening. They’re not science fiction; they’re not cold titanium beings mining asteroids.
They look like a radiologist in Ohio who caught a tumor because the model flagged something she might have missed on hour six of her shift. They’re a grandmother in rural Guatemala who can hear her grandchild’s voice read a book aloud in her native language because a model learned it from the last four speakers. They’re a power grid in Texas that didn’t fail because a word-predictor noticed a pattern in the load data three hours before the surge.
That’s the ‘pro’ move. Not building a god, building a better hammer and giving it to people who know what they’re building.
The tragedy of this moment isn’t that we built something dangerous. It’s that we built something full of potential and immediately shoved it into the exact same systems of power and violence that have been running things since before any of us were born.
We took a tool that could help us preserve languages, cure diseases, and keep the lights on. And we pointed it at schools in Iran instead. That’s not a technology problem, that’s a *choice* problem. We can make different ones.
I can hear the objection coming already because it’s a reasonable one: “But you just described the military’s entire argument.. Feed it enough intelligence and it can find the pattern - that’s what they’re doing with Grok!”
Here’s the distinction that matters, and I need you to hear it plainly.
In medicine, the radiologist checks the model’s flag. In infrastructure, the engineer verifies the prediction. In drug discovery, the lab confirms the candidate. The feedback loop is intact — when the model is wrong, someone finds out, and the system improves. The ground truth is knowable. The environment isn’t trying to deceive the model; a tumor doesn’t run a camouflage campaign to look like healthy tissue. Warfare inverts every single one of those conditions.
The battlefield is adversarial by design. The enemy actively works to look like something they aren’t. Decoys, misinformation, camouflage — the model is pattern-matching in a domain where the patterns are *designed to be misleading*. The feedback loop doesn’t exist because the evidence of error is destroyed along with the target. And the cost of a false positive is not a re-check. It’s a crater where an apartment building or hospital used to be.
Pattern-matching is powerful, but it requires conditions that warfare cannot provide: a cooperative environment, an intact feedback loop, and consequences that begin with a question rather than ending with an explosion.
That is the difference, not the technology. The conditions under which it operates.
Moët & Chandon in her pretty cabinet / A built-in remedy for Khrushchev and Kennedy
Dearest reader, when we started this piece I was angry, hurt, dismayed. I still am.
The human casualty is already incredible and will haunt us for generations, the knowledge that we did it using tools we designed to be helpful, to build our world and to be thoughtful, are being used in such ways.
It hurts in a way that I find hard to put into words - yet, sitting with that hurt is the whole point. If it doesn’t hurt, you’re not paying attention.
Here is what I’ve learned writing this: The predictive models we’ve built are powerful, but they are not what we think they are. They do not think, they do not reason, they do not understand. They pattern-match with astonishing speed and fluency, and they sound like they know what they’re talking about. That is their magic and their danger wrapped into one.
The question was never whether these machines could think - they can’t. The question was whether we could keep our heads straight while surrounded by something that produces such convincing text/output.
The military’s theory of AI warfare is seductive in its simplicity: feed the machine enough data, let it find the patterns, pull the trigger. It sounds like progress. It sounds like precision. It sounds like we’ve finally built the oracle that will keep us safe - but an oracle that hallucinates, that can’t tell you how many R’s are in a word, that agrees with whatever you ask it.. That is not an oracle. It’s a mirage, one we’re spending billions to chase and thousands of lives to feed.
What you can do about this right now is simple. Ask the strawberry question more often.
When someone tells you an AI “knows” something or “understands” a situation, ask yourself: can it count the R’s in strawberry reliably every time by knowing how to count? If the answer is no, then whatever it’s telling you about the target, the threat, the decision? Treat it with the skepticism it deserves. That’s not Luddism, it’s literacy. It’s understanding the tool well enough to know when it’s being misused. Pay attention to where these models are deployed and who’s deploying them.
The pipeline from a $20/month chatGPT interface to a missile targeting system is shorter than any of us realized, and it runs on our taxes and our attention. The companies building these tools are making choices about who gets access and for what purpose. Those choices have consequences. We should demand better ones.
The technology itself is not the enemy here, it’s genuinely remarkable with serious untapped potential: the “automated” in your “fully automated luxury gay space communism”. It can help us find tumors, preserve dying languages, keep the power grid stable, teach our children, be our partners in crime, and so much more. It doesn’t need to be misused like we’re applying it today in its infancy.
That’s not hype, that’s already happening in laboratories, operating rooms, classrooms and control rooms that you can walk into today. The tragedy is not that we built it, it’s that we immediately handed it to the same institutions of power and control that have been running the same plays since long before any of us were born, and we let them kill again, like they have before.
We have an obligation to be smarter than the tools we build - right now, we’re failing that obligation, not because the machines are too smart but because WE have convinced ourselves they are. The answer isn’t to unplug, though disconnecting has its purposes. The answer is to see clearly, to demand better, and to point these engines at problems that deserve their power, not people who can’t defend themselves from the impacts.
The future is not yet written. We still get a say in what it looks like. Let’s make it one worth living in, and let’s stop pointing our best tools at the worst possible tasks for a fucking change.
– RS
Rick, I just tried to find you and that was by simply clicking "subscriptions," which sounds pretty straightforward to me (but what do I know). I went as far down the list as I could. Even stuff I rarely or never open was coming in before you. In fact I MYSELF came in, yep: all the way down on the list. You are even harder to find than I can find -not -myself. If that makes any sense.
But, hey, I read a lot of it and it is the best take-down of ai I have yet read. No, it does not think. I never really put it that way. And you are making the right connections between obvious facts like the fact that Iran is the historical religious ENEMY of all these other gulf states and Iran's enemies are the ones who developed and used ai, etc. etc.
All very good stuff. There is therefore the following questions, and here are my notes for you:
At some point, we need to accept that human beings are unbelievably absurd. They always tend to believe they are scientific, and call themselves "human." They are actually "hyumin" (or Um, homo sapiens), a more humble designation. The hyumins who insist on being called "human" (or the Latin term as above but we do not have italics on 'Comments' due to the extreme wisdom of Chris, Hamish and whomever else they hired) are tenacious as hell and end up calling themselves "scientists."
However, they (their) hyumanity (or huminity) shows through. Well, that is a problem, isn't it?
The strategy these wunderkinds (again: no italics available due to incredible foresight/wisdom of the computer programmer) come up with is to divert our attention, directing it to machines. Computers come, artificial intelligence comes. How does that come out? IT murders people.
If they just called themselves hyumins, none of this would happen. WE assumed (wrongly) that they is human. They are not human. They arrogant ---- dumber than anything.
Who created MK Ultra? Those who call themselves *humans*. If they call they selfs "hyumin" it would have been different.
I seem really stuck on this , don't it? Well, anyhow...
We must care about our fellow hyumins ---- not our digital gigabytes.